Anthropic did not replace Git because Git suddenly became bad software. It replaced Git because Claude changed the unit economics of software development inside the company.
In May 2026, Anthropic merged roughly 2,500 code changes per day. By September, that figure had climbed above 30,000. The company’s monorepo had accumulated almost 100 GB of main-branch history, a compressed working copy exceeded 25 GB, and continuous integration systems performed about 25 million code checkouts every day. Fetching a complete compressed working copy for each checkout would have moved more than 600 petabytes of Git data daily.
The numbers forced Anthropic to confront an architectural mismatch. Git is a distributed version control system built to give every developer a capable, independent repository. Anthropic’s dominant clients were no longer developers working offline on laptops. They were agents and automated jobs running inside connected data centers, generating changes faster than human-oriented source control infrastructure could ingest, distribute, and validate them.
Anthropic’s answer is Scion, an internal source control system deployed across the company’s monorepo in five months. A seven-person team built Scion, its Antique code review system, and several related tools during that period. Scion abandons several of Git’s defining assumptions: clients do not receive the full repository graph, graph operations happen on servers, files materialize only when requested, and the normal development path discourages branches and tags other than the main reference and release branches.
Scion is not “Git, rewritten faster.” It is a different division of responsibility between the client, the source control service, and the surrounding development platform. That distinction makes Scion technically interesting even for organizations that should keep using Git—which is almost everyone.
Git’s Strength Became Anthropic’s Scaling Cost
Git’s architecture reflects the conditions under which it became dominant. A clone is a self-contained repository. The client can inspect history, calculate diffs, create commits, switch branches, identify merge bases, and perform most other operations without asking a central server. That independence makes local work fast, protects developers from network outages, and prevents a hosting provider from becoming the sole owner of repository history.
The independence has a price. Each clone needs enough repository state to perform those operations. Git reduces transfer and storage costs through content addressing, compression, delta encoding, shallow clones, partial clones, sparse checkouts, and packfiles. At ordinary scale, the trade is excellent. Even large organizations can extend it with repository mirrors, cached snapshots, and specialized hosting infrastructure.
Anthropic used those techniques. At peak, it operated several hundred internal Git mirrors. The company also distributed repository snapshots, or seeds, through blob storage so that a new job could begin from a recent copy rather than cloning the entire repository from scratch.
Agent workloads eroded the value of both mitigations. A seed is useful only while it remains close to the current main branch. At 30,000 merged changes per day, a snapshot becomes stale quickly. Every consumer must then fetch the gap. History-dependent operations such as blame and diff become harder to preserve when clients hold incomplete views of a rapidly changing graph.
The mirrors had a different failure mode. A Git server does substantial work to negotiate the objects a client lacks and produce packfiles that transfer those objects efficiently. Hundreds of mirrors can spread that work, but each mirror remains a stateful repository with disk, memory, synchronization, and maintenance requirements. Anthropic’s monorepo eventually exceeded practical resource boundaries for the mirrors themselves.
The deeper problem was duplication of capability. Every agent sandbox received repository machinery designed to support an autonomous human developer, even though the sandbox was always online and often needed only a small directory or a single source control answer. A continuous integration job asking for the diff between a changeset and its merge base did not inherently need a local repository. Git’s normal operating model made that local state the price of asking the question.
At human development speed, the price is usually inconsequential. At 25 million checkouts per day, it becomes an infrastructure product in its own right.
Scion Moves Intelligence to the Server
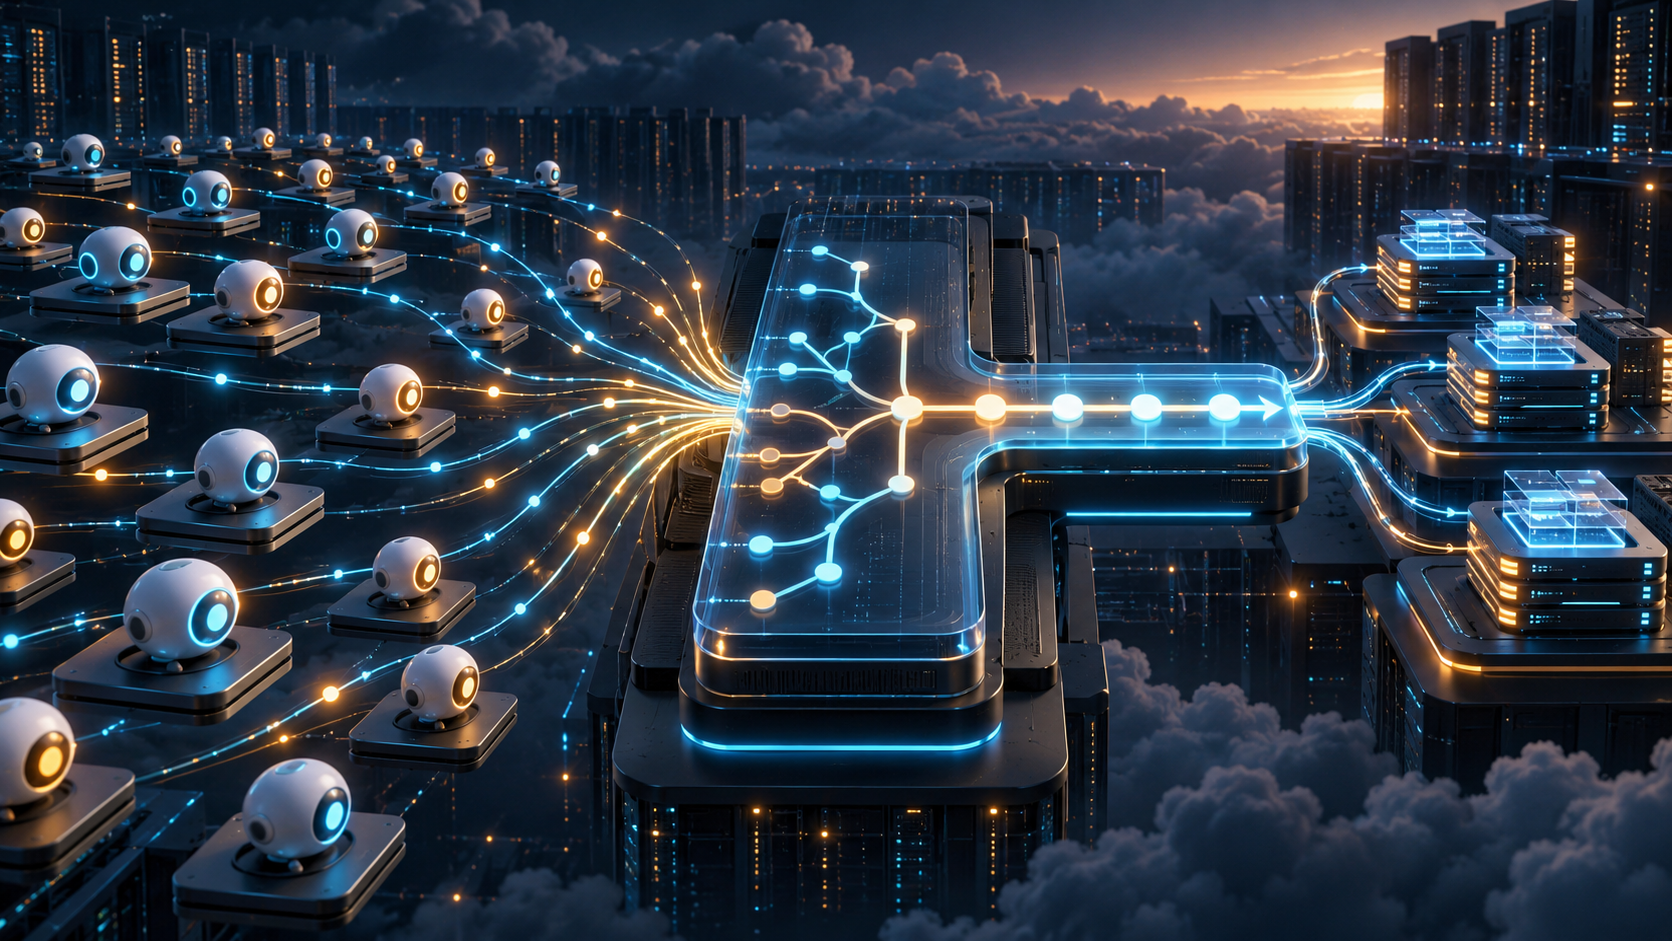
Scion starts with an assumption that Git deliberately avoids: the client can depend on the network. Anthropic’s agents, research jobs, and continuous integration runners already execute inside managed infrastructure. They do not need offline source control. Once constant connectivity becomes an acceptable constraint, the server can perform operations that Git delegates to every clone.
The Scion client, called scn, maintains a bounded object cache, lays files out in a working copy, detects local filesystem changes, and gives users an interface to the service. It does not contain a complete repository and cannot independently provide the full set of graph operations. Scion’s servers create commits, perform merges and rebases, calculate diffs, resolve merge bases, and answer history and blame queries.
That asymmetry changes how other systems consume source control. Anthropic exposes the same server-side operations through application programming interfaces. A tool that needs ancestry, blame, or diff data asks the source control service directly. Automated bisect and revert pipelines can operate against those APIs without maintaining millions of local repository copies.
Scion’s primary record is a changeset, stored as an entry in a write-ahead log. A Git commit points to a complete root tree, which recursively identifies the repository snapshot. A Scion changeset instead records the paths changed relative to its first parent and content-addressed pointers to compressed file contents in blob storage.
The design makes ingestion incremental. Creating a changeset scales with the size of the change instead of the size of the repository. Changesets do not arrive as packfiles, and creation does not require moving a branch reference or coordinating across every source control server. Once the server accepts a changeset, it is globally available.
Scion still supports references, but Anthropic discourages them outside the main reference and release branches. When a reference does move, Scion uses a compare-and-swap operation on a single row in Google Cloud Spanner. Changeset creation and reference movement are separate operations, which keeps the high-volume ingestion path free of a shared branch lock.
The changeset record is intentionally incomplete. A list of modified paths cannot immediately answer who last touched a line, which commits affected a file, or how to move efficiently through a deep commit graph. Scion constructs dedicated derived structures for those questions, including blame data, path history, graph skip lists, copy detection, and path-based search.
Each derived structure is defined recursively from the corresponding values of a changeset’s parents. Anthropic can calculate a structure eagerly when latency demands it or defer the work until a client asks. Because the structures remain behind the service API, the implementation can change without requiring a client upgrade or a repository-format migration.
This separation is one of Scion’s most consequential choices. Git stores enough general-purpose structure in every clone to let the client derive many answers locally. Scion stores a compact authoritative event and materializes specialized indexes centrally. Anthropic has traded client independence for operational control over when, where, and how computation occurs.
Immutable Objects Make the Cache Hierarchy Work
Moving work to servers could have created a new bottleneck. Scion avoids replacing thousands of heavy clients with a handful of overloaded authoritative servers by making immutable, content-addressed data easy to cache at multiple layers.
The scn client does not negotiate a giant response by describing every object it already holds. It starts from the requested root tree, checks its local store, asks for missing trees, and repeats the process for the blobs it actually needs. Each request names a specific object whose contents never change. Any cache holding that object can answer without consulting a leader or checking whether its copy is current.
That property supports Anthropic’s tiered serving topology:
- The client uses a bounded local cache and asks only for requested trees and blobs.
- A
scion-daemonon the compute node shares cached objects across agent sandboxes and jobs on that node. - Regional
scion-cacheservers stream objects from memory in the on-disk format the daemon expects. - Authoritative
scion-serverinstances read metadata from Spanner and file contents from cloud object storage when an upstream cache misses.
All three server-side tiers answer the same remote procedure calls. The client does not need to understand the topology. Anthropic nevertheless enforces the tiers so that a regional cache failure cannot send the entire fleet directly to the authoritative service and turn a localized incident into a system-wide overload.
Scion’s fetch path also avoids delta-compressing an individualized packfile for each client. The regional cache can serve a preformatted immutable object directly from memory. Requests are individually resumable, and sparse operation is native: if a client does not need a subtree, it never requests that tree. A virtualized checkout can delay file materialization until a process actually opens the file.
Anthropic reports cache hit rates above 99% at every tier. The company says Scion’s CPU and memory footprint is 200 times smaller than the Git mirroring infrastructure it replaced. Checkout times fell by two orders of magnitude—from minutes to seconds—and the change released 25% of the CPU capacity previously consumed by continuous integration.
Those gains do not come from a universally superior encoding. They come from aligning the protocol with a highly repetitive fleet. Many jobs on the same node request the same repository state. Many nodes in the same region request the same immutable objects. A shared cache extracts value from that overlap instead of asking each ephemeral sandbox to reconstruct and maintain its own repository.
Source Control Was Only One Part of the Migration
Scion’s architecture removes assumptions embedded throughout the rest of the software development lifecycle. Anthropic therefore had to build more than a storage service. The same seven-person team also produced Antique, a code review surface, alongside code search, identity and access management, migration tooling, and integration systems.
The coupling explains why Anthropic does not plan to release Scion as a general Git replacement. A company adopting it would need to migrate code review, continuous integration, search, permissions, and every internal tool that expects Git objects, references, commands, or repository layouts. Anthropic’s versions of those systems are bespoke to its monorepo and infrastructure.
The migration also changed how Anthropic thinks about validation. A conventional merge queue tries to establish that a proposed change passes against a known version of the main branch before moving the branch pointer. When hundreds or thousands of other changes can land during one test run, that guarantee becomes expensive and increasingly artificial. The tested revision may already be far behind main by the time the suite finishes.
Anthropic has shifted investment toward post-merge and pre-deployment testing rather than relying on a global repository lock. Concurrent changes can conflict or combine into a regression after landing. Automated systems then need to identify, bisect, revert, or repair the failure quickly enough to keep main usable and unsafe code away from production.
That model changes the control objective. The source control layer maximizes safe ingestion and traceability, while later gates determine deployability. It can work only when the organization has excellent observability, reliable automated rollback, strong deployment separation, and enough test isolation to prevent a bad merge from becoming a customer incident.
Scion and Antique add controls suited to that operating model. Scion supports repository- and directory-level permissions so that sensitive code can remain inside the monorepo without being visible or writable everywhere. Antique can express semantic approval constraints that distinguish low-risk changes, such as comments, from logical changes affecting sensitive code. Anthropic says human engineers still review every change request, but reviewers increasingly evaluate intent rather than reading every generated line.
The final point deserves caution. Intent review is not a general substitute for code review. It depends on the quality of tests, policy enforcement, generated-code evaluation, deployment controls, and the particular risk of the system being changed. Anthropic’s account describes its own internal practice at an unusual scale; it does not establish that ordinary teams can safely reduce line-level review.
Claude Accelerated Both the Problem and the Response
Claude’s coding throughput created the source control bottleneck, and Anthropic also used Claude to build the replacement. The company cites an early version of its Git-to-Scion ingestion pipeline as a striking example. An internal Claude model rewrote the prototype with 20 times lower memory consumption and four times higher speed while preserving implicit ordering and data-structure invariants.
The broader engineering account is more instructive than the benchmark. Anthropic’s engineers supplied the system boundaries, scale requirements, architecture, and tradeoffs. They also repeatedly stopped agents from satisfying a local task in ways that violated global constraints.
In one case, generated code tried to determine when a change had landed by scanning the commit log linearly instead of querying the code review system. The code could have returned the right answer and still been architecturally wrong at Anthropic’s scale. In another case, adversarial review pushed the implementation toward excessive defensive validation against a trusted internal service. Human engineers had to recognize that the extra complexity did not justify its cost.
These examples expose the governance problem hidden inside agentic development. An agent can optimize a function, implement a request, or answer a review comment without carrying the organization’s complete architectural model. Higher code volume amplifies every missing constraint. Teams need machine-readable interfaces and policies, but they also need engineers with enough system context to reject locally plausible changes.
Anthropic applied agents to operations as well. Dedicated Claude instances, nicknamed “superfans,” monitor telemetry and logs for individual Scion components and look for unusual behavior. Traditional alerts still exist. The agents supplement threshold-based monitoring by searching continuously for patterns that operators did not encode in advance.
The Scion story is therefore not a clean tale of automation replacing engineering. It is an example of engineering moving upward: less time producing syntax, more time defining invariants, interfaces, failure domains, and acceptable operational behavior. Anthropic’s seven-person team could move quickly because agents generated and evaluated large volumes of implementation work. The small human team remained responsible for deciding what kind of system should exist.
What Other Engineering Organizations Should Take From Scion
Anthropic explicitly says Scion is unsuitable as a general replacement for Git. Its design makes sense for enormous monorepos served to tens of thousands of engineers or fleets of agents. Anthropic also spends far more on internal model inference than most businesses could justify. Those caveats are central to interpreting the announcement.
For most teams, Git is not yet the bottleneck. Poor task boundaries, weak tests, slow builds, flaky continuous integration, uncontrolled agent permissions, and inadequate review discipline will constrain useful agent throughput long before packfile generation does. Replacing source control would add migration risk without correcting any of those problems.
Scion still offers a practical diagnostic framework. Teams scaling agentic development should measure where work accumulates instead of assuming code generation is the only relevant throughput metric:
- How much data does each ephemeral environment download before useful work begins?
- How often do agents fetch repository history they never query?
- How many concurrent tasks duplicate identical objects on the same host?
- How stale is a proposed change by the time pre-merge tests finish?
- Which source control questions could a forge answer through an API without a checkout?
- How quickly can the organization detect, bisect, revert, and contain a bad merge?
- Can access policies limit agents to the directories and operations their tasks require?
Organizations approaching checkout or storage limits can exhaust Git-native options first. Partial clones can omit file contents until they are needed. Sparse checkouts can restrict the working tree to relevant directories. Shared object stores and prepared snapshots can reduce repeated downloads. Ephemeral worktrees can isolate concurrent agent tasks without giving every task a wholly independent clone. Server APIs can answer common metadata questions without local graph traversal.
The architectural direction is more important than any single command. Agent environments should receive the minimum repository state and authority required for a task. Expensive shared operations should move toward services that can cache, govern, and observe them centrally. Validation should distinguish between accepting a change into source history and allowing that change to reach production. Source control, continuous integration, code review, and deployment must be designed as one throughput system.
Scion also suggests where Git hosting may evolve. A Git-compatible platform can preserve familiar clients while developing asymmetric server implementations, richer source control APIs, better composition of sparse and partial features, and storage architectures that do not require every serving node to hold a fully materialized repository. The choice is not limited to unchanged Git or a proprietary clean-sheet replacement.
The industry’s source control infrastructure was tuned for the rate at which humans write and review code. Agents have increased the arrival rate of changes without automatically increasing the capacity of checkout, testing, review, integration, and deployment systems. Anthropic reached the resulting bottleneck early because it operates at an extreme scale.
Scion’s most useful lesson is not that Git’s era has ended. It is that software delivery has become a queueing problem across the entire development lifecycle. Faster code generation shifts pressure downstream. Organizations that deploy agents successfully will redesign those downstream systems deliberately, preserving human judgment where consequences concentrate and removing duplicated machinery where automation no longer needs it.