Anthropic’s announcement that future Claude models will watermark generated text sounds simple: Claude will leave an invisible signal in its writing, and someone with the right detector can estimate whether Claude helped produce it. Because the signal lives in the sequence of word choices, copying the text does not inherently remove it. The watermark adds no hidden characters, identifying account data, or extra tokens. Anthropic also says its testing found no practical effect on output quality.
The mechanism is real, useful, and easy to misunderstand.
A text watermark is not a signature attached to a document. It is a statistical pattern distributed across token choices during generation. It can support a claim that a compatible model probably produced enough of the text. It cannot establish who prompted the model, whether the output is true, whether a person substantially revised it, or whether using AI violated any rule.
That distinction has become operationally urgent. Article 50 of the European Union’s AI Act now requires providers of systems that generate synthetic audio, images, video, or text to make their outputs machine-readable and detectable as artificially generated or manipulated. The European Commission’s implementation guidance describes marking as a provider obligation and separately assigns disclosure duties to deployers in cases such as deepfakes and public-interest text without human review or editorial control.
The law does not turn a watermark into a verdict. Neither should an employer, university, publisher, court, or security team.
A Watermark Lives in the Generation Process
Plain text has no durable metadata channel. A JPEG can carry an embedded manifest. An audio file can contain a signal shaped into its waveform. A text file is essentially a sequence of characters. Zero-width Unicode characters and similar tricks can be removed by sanitization, retyping, or a routine copy-and-paste workflow.
Modern text watermarking therefore changes how the model chooses words.
A large language model does not compose a finished paragraph and then reveal it. It repeatedly calculates a probability distribution over possible next tokens. A token may be a whole word, part of a word, punctuation, or another unit from the model’s vocabulary. The model then selects one token, appends it to the context, and calculates the next distribution.
Suppose a model has written, “The weather remained cold and …” Several continuations may be defensible. “Grey,” “overcast,” and “windy” could each receive meaningful probability. A watermarking algorithm uses those moments of flexibility to make token selection follow a secret, reproducible pattern.
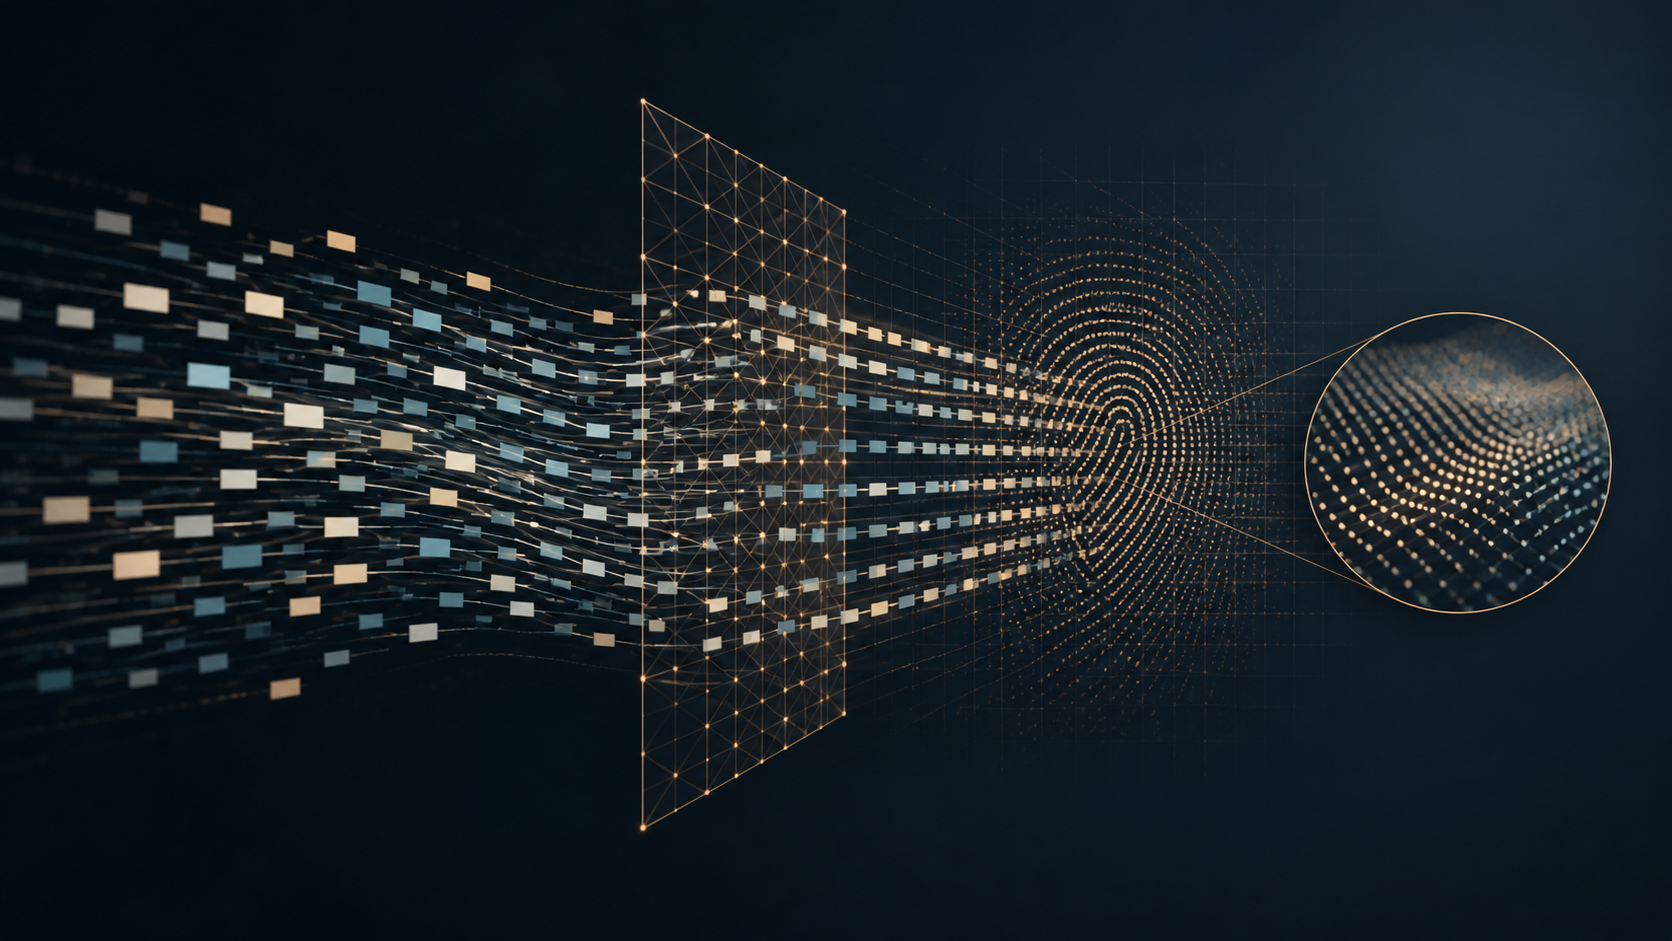
The influential watermarking framework introduced by John Kirchenbauer and colleagues illustrates the basic design. At every generation step, a pseudorandom function uses a secret key and recent tokens to divide the vocabulary into changing groups. The algorithm slightly increases the scores of tokens in a favored, or “green,” group. It does not have to ban every other choice. The normal model distribution still constrains the output, while the bias makes favored tokens appear more often than chance would predict.
The favored group changes with the context. A token favored after one phrase may not be favored after another. That context dependence prevents the watermark from becoming a fixed vocabulary or a list of telltale AI words.
Detection replays the process. Given the text, its tokenizer, the watermark configuration, and the secret key, the detector reconstructs which tokens would have been favored at each position. It counts how often the observed text followed the pattern and compares that count with the rate expected by chance. A common formulation is a z-score:
Here, is the number of eligible token positions, is the number that land in the favored set, and is the expected favored fraction for unwatermarked text. A larger score means the observed pattern is less likely to have arisen by chance under the detector’s assumptions.
Google DeepMind’s SynthID-Text research uses a more sophisticated tournament-based sampling design, but the governing idea is similar: alter token sampling in a controlled way, then test the resulting sequence for the expected statistical pattern. Google says SynthID can preserve the model’s output distribution while creating a detectable signal, and it uses repeated-context masking to avoid reinforcing a watermark when the same context appears again.
Anthropic describes Claude’s method in accessible terms. A key and preceding words change the source of randomness used for low-stakes choices. The resulting pattern can be evaluated by a detector that knows the key. Anthropic says the pattern contains no user, organization, conversation, prompt, or timestamp identifier. It is therefore a Claude-involvement signal rather than a tracking tag.
That privacy property narrows what the system can prove. A detector might conclude that a passage is statistically consistent with Claude’s watermark. It cannot use the watermark alone to connect the passage to Josh, Alice, a particular API key, or a specific chat.
Detection Confidence Depends on Available Choices
Watermarking needs entropy: the model must have several acceptable next-token choices. The watermark has room to operate in a long essay, story, marketing draft, or conversational answer because many sentences can be expressed in several reasonable ways.
Low-entropy output provides less room. A short factual answer, quotation, mathematical derivation, or exact code fragment may contain token positions where only one continuation is correct. A responsible watermark must yield to accuracy rather than force an arbitrary favored token. Every yielded position reduces the evidence available to the detector.
Length compounds the problem. A statistical test needs enough observations to separate a real bias from random variation. A long response can accumulate a strong signal across hundreds of choices. A sentence or short paragraph may not. Anthropic explicitly says its watermark works best on longer, varied text and is less reliable on short or constrained outputs. Google makes the same limitation explicit for SynthID-Text: it works best on longer, diverse generation and is less effective for factual prompts with little expected variation.
Editing changes the sample too. Deleting a paragraph may leave enough watermarked tokens for detection. Replacing a few words may weaken the score without erasing it. Thorough rewriting, translation, or paraphrasing can substantially reduce confidence because the detector no longer sees the original sequence of token decisions. Google states that translation and extensive rewriting can greatly reduce SynthID confidence. Anthropic likewise acknowledges that a sufficiently determined person can remove a text watermark.
The asymmetry is unavoidable. The watermark must be subtle enough to preserve useful writing, which means it is a weak perturbation rather than an indelible mark. An adversary can ask another model to paraphrase the output, translate it through another language, or extract the claims and write a new version. The content may remain recognizably derived from the original while the generation trace disappears.
The inverse problem is equally important. A positive signal applies to the analyzed sequence, not necessarily every statement within it. Someone can preserve a long watermarked passage while inserting false, defamatory, or malicious claims. If the aggregate signal remains strong, an unsophisticated consumer could attribute the entire composite to the model provider. Robustness to benign edits and vulnerability to malicious splicing are two sides of the same design choice.
Detector access introduces another tradeoff. Keeping the detection key private protects it from straightforward evasion and forgery, but verification then depends on the provider. Exposing a score through an API gives third parties access without releasing the key, yet repeated, carefully modified queries may reveal information about favored token choices. The API also becomes a sensitive-data boundary: submitting an unpublished legal brief or incident report to an external detector may create a worse governance problem than the watermark resolves.
Rate limits, coarse result categories, abuse monitoring, and carefully designed privacy controls can reduce those risks. They do not eliminate the underlying tension between public verification and secret detection logic. Research into zero-knowledge verification may eventually allow a provider to prove that it ran a detector correctly without revealing the watermark key, but such systems add cryptographic and operational complexity and are not what Anthropic announced for ordinary Claude users.
The EU AI Act Requires Marking, Not Omniscience
Article 50 creates several obligations that are frequently collapsed into the single word “watermarking.” The separation is important.
Providers of interactive AI systems must design them so people know they are interacting with AI, unless that fact is obvious from the circumstances. Providers of systems that generate synthetic content must mark outputs in a machine-readable format and make them detectable as artificially generated or manipulated. Deployers face disclosure duties for emotion-recognition and biometric-categorization systems, deepfakes, and AI-generated or manipulated public-interest text under defined conditions.
For public-interest text, Article 50 includes an exception when the content has undergone human review or editorial control and a person or organization holds editorial responsibility for publication. That exception concerns the deployer’s disclosure obligation. It does not convert lightly edited AI text into human-authored text, and it does not erase the provider’s marking obligation at generation time.
The regulation also builds proportionality into provider marking. Techniques must be effective, interoperable, robust, and reliable as far as technically feasible, taking account of the content’s nature, implementation costs, and the generally acknowledged state of the art. Standard editing functions and AI assistance that do not substantially alter the input or its meaning receive separate treatment. The statutory language recognizes that a universal, attack-proof detector does not exist.
The Commission’s voluntary Code of Practice supplies a practical route for demonstrating compliance. A provider that does not follow the Code must be able to demonstrate equivalently adequate measures. The Code is evidence of a compliance approach, not a declaration that any particular watermark is infallible.
Penalties explain why providers are moving now. Violations of operator obligations that include Article 50 can fall within the AI Act’s administrative-fine tier of up to €15 million or, for an undertaking, up to 3 percent of total worldwide annual turnover for the preceding financial year, whichever is higher. Actual enforcement will still depend on the facts, the responsible authority, proportionality, and the Act’s penalty provisions. “Up to” should never be rewritten as an automatic fine.
The legal requirement also does not mandate a cryptographic signature for every text output. Article 50 requires machine-readable marking and detectability. A statistical token watermark can satisfy that design objective without attaching a signed identity record. Calling every watermark a cryptographic signature confuses three different systems:
- A statistical text watermark biases generation and supports probabilistic detection.
- Cryptographically signed provenance metadata records claims about a file and allows tamper detection while the metadata remains attached.
- A visible disclosure tells a person that content was generated or manipulated by AI.
Each control answers a different question. Combining them can provide stronger coverage, but one cannot silently substitute for another.
Text Watermarks and Content Credentials Solve Different Problems
For images, audio, and video, providers can layer embedded signals with provenance metadata. The Coalition for Content Provenance and Authenticity (C2PA) specification supports signed manifests commonly presented as Content Credentials. A manifest can record who or what made a provenance claim, the tools involved, and transformations in the asset’s history. Cryptographic signing makes later tampering with the manifest detectable.
C2PA does not prove that the depicted event happened. It proves the integrity and source of specific provenance assertions, subject to trust in the signer, its certificate, its key management, and the capture or generation workflow. A perfectly valid manifest can describe synthetic media. A photograph without a manifest may still be authentic.
Metadata is also detachable. A platform may strip it during upload or transcoding. A screenshot can preserve visible pixels while leaving the original manifest behind. C2PA has mechanisms for durable credentials and recovery, but no metadata ecosystem can force every intermediary to preserve every assertion.
Signal-level media watermarks address a different failure mode. Google describes SynthID as embedding imperceptible patterns into generated images, audio, video, and text. Image and video signals are designed to survive common transformations such as compression, cropping, filters, and frame-rate changes. Audio signals are designed to tolerate changes such as MP3 compression, noise, and speed adjustment. “Designed to survive” is not the same as impossible to remove; sufficiently destructive transformations can defeat detection or destroy the media’s usefulness along with the signal.
Text cannot use the same pixel or waveform channel, so its watermark is bound to wording. If someone rewrites the wording while preserving the idea, the original statistical evidence can vanish. This makes text provenance uniquely dependent on the boundary between generation and subsequent authorship.
Organizations should therefore resist building a single universal field called ai_generated. A more defensible provenance record distinguishes at least:
- which detector or credential system produced the result;
- which model family and watermark version it can recognize;
- the text or file hash that was actually evaluated;
- the result category and confidence or threshold;
- the date of evaluation and detector version;
- transformations known to have occurred before evaluation;
- whether the evidence is provider-controlled, independently verifiable, or cryptographically signed;
- the policy decision made after human review.
Without that context, a database full of “AI detected” labels is forensic debt wearing a compliance badge.
A Watermark Is Evidence, Not a Disciplinary Decision
The most dangerous deployment is not watermarking itself. It is an institution treating detector output as a complete adjudication system.
A positive result can support the proposition that Claude was involved in producing or processing enough of the analyzed text to leave the expected pattern. Anthropic states that the watermark cannot distinguish between Claude writing a passage and Claude heavily editing it. The result also does not establish plagiarism, deception, policy violation, or lack of human contribution. A user may have been authorized to use AI. A human may have supplied the ideas, evidence, structure, and final edits. A malicious actor may have inserted harmful text into a watermarked passage. The detector cannot resolve those questions.
A negative result is weaker still. It may mean the text was human-written, generated by an unwatermarked model, too short to classify, heavily edited, translated, paraphrased, or produced in a low-entropy task where the watermark could not accumulate. “No watermark detected” cannot responsibly become “no AI was used.”
This is why watermark detectors should not replace broader evidence. In an academic-integrity case, relevant evidence might include drafts, revision history, citations, oral explanation, assignment-specific policy, and the student’s working process. In an enterprise leak investigation, investigators might examine access logs, model gateway records, document history, data-loss-prevention events, and endpoint evidence. The watermark can enrich a case. It should not become the case.
The same principle applies to public misinformation. A watermark says something about origin, not truth. Human beings publish falsehoods. Models produce correct statements. Provenance helps readers interpret content, but factual verification remains a separate job.
A defensible organizational control has several parts:
- Define allowed and prohibited AI uses in terms of data, decisions, and accountability rather than the mere presence of generated prose.
- Treat watermark results as one evidence source with documented uncertainty.
- Preserve the exact artifact, detector version, configuration, output, and chain of custody.
- Require human review before adverse action.
- Give affected people a meaningful way to contest the evidence and provide process records.
- Prohibit submission of confidential material to external detectors unless privacy, retention, training use, and contractual terms have been reviewed.
- Revalidate controls as models, watermark keys, detectors, thresholds, and regulations change.
These controls sound more cumbersome than installing an “AI detector” browser extension because they are the work of governance. The browser extension is the easy part.
Provenance Is a System, Not a Stamp
Anthropic is right to describe watermarking as a way to estimate Claude’s involvement rather than a way to identify a user. Its announcement also states the crucial limitations: detection works better on long and varied text, constrained outputs provide less signal, and a motivated person can remove the watermark. Those caveats do not make the technique useless. They define its legitimate use.
Text watermarking can improve transparency at scale for ordinary, unmodified output. It can give platforms and auditors a higher-quality signal than generic style classifiers, because the provider intentionally created the pattern during generation. It can help providers meet a real regulatory obligation without adding visible clutter or personal identifiers to every response.
It will not end unattributed AI use. It will not authenticate facts. It will not preserve provenance through unlimited transformation. It will not eliminate the need for editorial responsibility.
The durable architecture is layered. Use provider-side marking to establish a generation signal. Use signed provenance records where file formats and workflows can preserve them. Use visible disclosure where people need immediate context. Maintain system logs where organizations need accountability. Preserve human review for decisions that affect rights, reputation, employment, education, or access.
Watermarking is strongest when it makes a narrow claim and the surrounding governance refuses to inflate it. The signal can tell us that a pattern is present. Responsible institutions must still decide what that pattern means.